Tokens per task
Model providers set the price of a token. They do not set how many tokens your task uses.
The industry cut the price of a token. We cut how many a task uses. Placeholder AI sits between your data and the model and passes on only the context that request needs. Processing and storage stay in Europe.
You send a workload. We send back the numbers, and how we got them.
Fall in the price of a token since 2022. Your bill went up anyway.
More tokens burned per task once workloads become agentic.
Lower cost per completed task with our architecture, at ≥ 95 % of frontier output quality.
01 The problem
A conventional setup sends the model everything it might need, on every request. An agentic task is dozens of those requests, so you pay for that waste over and over.
The bill is still a frontier-model bill, for work that never needed frontier reasoning.
02 What we build
A brain-inspired knowledge network sits between your data and the model. It does what memory does: keeps what matters, drops the rest, and ties related facts together before the model sees them.
Each request gets the context that task needs, with the links between those facts already in place. A similarity search would have passed along every passage that scored well enough.
It works like a library index. You look up the shelf you need. You don't copy the whole library for one question. With less to read, a smaller model can match frontier output on your workloads.
03 Why it holds
A vendor can give you a discount. They can also take it back.
Model providers set the price of a token. They do not set how many tokens your task uses.
We change what the model reasons over. Shrinking the prompt stops working the moment context windows get bigger.
The knowledge network gets better with use. Accuracy goes up without retraining, and the second deployment in a sector starts ahead of the first.
Processing and storage stay in Europe. That is how the system is built, not a deployment option you switch on.
04 What it's worth
How many agents you run, how many turns each one takes, and whether a turn is small, medium or large. That fixes the tokens. Today's bill prices them at list rate, with prompt caching on the input. Ours is a flat 0.4 cent per turn.
Provisional. List prices and a flat fee, not a measurement. Send us a workload and we replace these assumptions with one.
One agent, started and finished. The default is a modest production volume.
Each model call inside that run, including tool steps you pay for today.
Tokens on each turn
How much the model reads and writes on one call. 80 % of that is input, 20 % is output.
Model you use today
Published list price, USD per million tokens. A cache read is 10 % of the input price. Medium is Sonnet.
Tokens this month
Estimated cost today
Sonnet · $0.20 read / $10 out
With Placeholder AI
0.4 cent per turn
€1,350 less each month.
Cost per agent run
Today
With Placeholder AI
2,000 runs × 50 turns = 100,000 turns. A medium turn is 8,000 tokens: 6,400 input and 1,600 output. The first turn writes all 6,400 input tokens to cache. On each later turn, 90% of input (5,760 tokens) is a cache read and 10% (640 tokens) is a cache write. Sonnet is $2 per million input tokens and $10 per million output tokens. A 5-minute cache write is $2.50 and a cache read is $0.20, converted at $1 = €0.92. That is 800,000,000 tokens this month. Placeholder AI is €0.004 per turn. Batch discounts and one-off integration are not included.
The 50 % figure elsewhere on this page is a measured cost per completed task. This estimate is volume at list price. The method is in Benchmarks & method.
05 Benchmarks & method
We run the same enterprise workloads twice. Once on a frontier model with a conventional setup, once on a smaller model with our architecture. Then we compare what it cost to finish each task, and how good the output was. That includes the workloads where we save less.
Most AI pricing is quoted per token, the unit the model reads and writes. A budget is not kept in tokens.
We measure one finished piece of work. Answering a customer enquiry end to end. Extracting the terms from a contract. Completing one agent run. We count every token used on the way, including retries, tool calls and intermediate steps, and multiply by the list price of the model.
Same tasks, same definition of done, two setups. We publish the difference.
Technical detail
[ To be published with the benchmark release. ]
| Workload | Type | Baseline model | Our setup |
|---|---|---|---|
| — | — | — | — |
| — | — | — | — |
| — | — | — | — |
The workloads come from real enterprise use. Public leaderboard tasks are not what shows up on the invoice. Each run states the model versions, prompts, retrieval setup and list prices, so the result can be recomputed later against the prices in force then.
[ To be published with the benchmark release. ]
| Workload | Cost / task, baseline | Cost / task, ours | Reduction | Quality vs. baseline |
|---|---|---|---|---|
| — | — | — | — | — |
| — | — | — | — | — |
| — | — | — | — | — |
Quality stays at the threshold. We cut cost underneath it. A cheaper answer that is worse does not count as a saving.
[ Scoring protocol to be published with the benchmark release. ]
This section will state the rubric for each workload type, who scores the output, how disagreement is handled, and the sample size behind each figure. You should be able to tell whether our “≥ 95 % of frontier quality” matches what you would accept.
Short, single-turn requests already carry little context, so there is little waste to remove. Workloads that are mostly raw generation, rather than retrieval and reasoning, benefit less. Tasks that need frontier-level reasoning still need a frontier model.
If your workload is one of these, we will say so before a pilot.
[ Harness and instructions to be published with the benchmark release. ]
We re-run the benchmark with every major model release. Until the harness is public, send us the workload you care about and we will run it against both architectures with you watching.
Coming soon. The measured results for each workload will be published here.
06 Where the data sits
The full inference stack runs on European infrastructure. No external API calls, and no customer data used for training.
European infrastructure means European operators. A data centre in Stockholm or Frankfurt still falls under US law if a US company owns and runs it. Ours is European in ownership and operation, not only in location.
It does not cost you performance, and it comes with the product. A security review covers the stack, and you clear compliance once.
ISO 27001 and SOC 2 are on the roadmap, not yet certified.
07 Why we exist
If frontier models stay affordable only for a handful of US and Chinese firms, European companies remain customers of that intelligence. They cannot inspect it, price it, or change it. Bringing the cost of a finished task down is how more of them get to build.
We would rather build it here.
Better thinking, not bigger machines.
08 Who we are
Placeholder AI is a German GmbH, founded in Munich in August 2026 and funded by the two of us. We stay small. It is hard to tell customers to do more with less while spending like we don't have to.
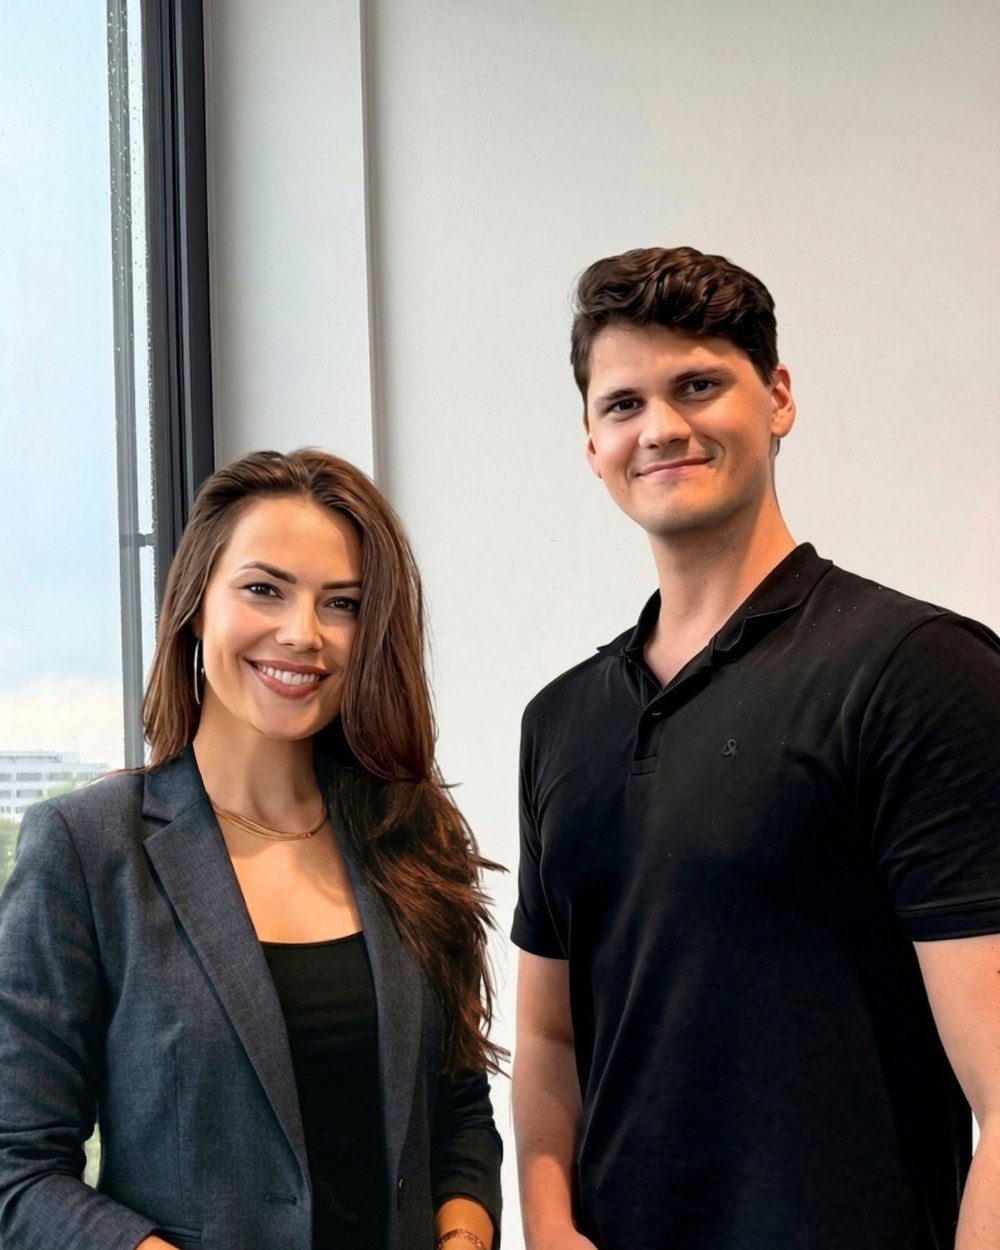
Co-Founder & CEO
Psychologist (M.Sc.), specialised in learning and memory. For the last few years she has worked with European companies on how they operate. She runs Placeholder AI's business: operations, strategy and go-to-market.
Co-Founder & CTO
Previously Head of Data & AI at a European consultancy, where he watched the economics break once pilots hit production volume. He designs and builds the memory and reasoning architecture.
09 Next step
Send us a workload you already run, and the model you run it on. We come back with cost per completed task for both setups, and the method behind each number. If the saving on your workload is small, we will say so.